Strict Programming Language

Strict Programming Language

  • Games
  • Performance
  • VS Code
  • Docs
  • Blog
  • GitHub

›All Blog Posts

All Blog Posts

  • Faster Inference, Better Memory Reuse and Smaller Builds
  • Strict Feels Alive — SCrunch, Qwen3-8B and C# Interop
  • Packages, Parallel Loops and Language Models
  • October 2026 Strict Compiles Itself
  • July 2025 New Strict parsing and runtime design overview
  • March 2023 Mutable
  • January 2023 Multi Line Text Expressions and Introducing New Lines in Strict
  • January 2023 Namings in Strict
  • December 2022 Traits and Components
  • November 2022 Multi Line List Expressions
  • November 2022 Strict Base and Example folders moved to separate repository
  • October 2022 Shunting Yard
  • September 2022 For loops
  • September 2022 Details about Mutability in Strict
  • July 2022 Introduction To Generics In Strict
  • June 2021 Slow Progress
  • May 2021 Strict Newbie Experiences
  • May 2021 BNF Grammar
  • May 2021 Next Steps
  • Jul 2020 Getting Back Into It
  • Jul 2020 Optimizing FindType
  • Jul 2020 Package Loading
  • Jun 2020 Parsing Methods
  • Jun 2020 As Simple As Possible
  • Jun 2020 Back to blogging
  • May 2020 Slow and not steady
  • Apr 2020 Sdk going open source
  • Feb 2020 Still work in progress
  • Jan 2020 website is up

Jul 2020 Optimizing FindType

July 5, 2020

Benjamin Nitschke

Still working on the package loading code from the last blog entry. The main issue was the dummy repositories system I build a few days ago to grab code from a fixed folder, which didn't exist on the CI server. So instead of hacking another quick solution, the code was changed to download any repository from github and provide it at a StrictPackages local cache folder. This works very well and is also efficient, but there are so many problems to be solved, not just the caching and when to redownload the cached folders, but a huge amount of testing and CI issues took a long time to fix: TeamCity CI issues
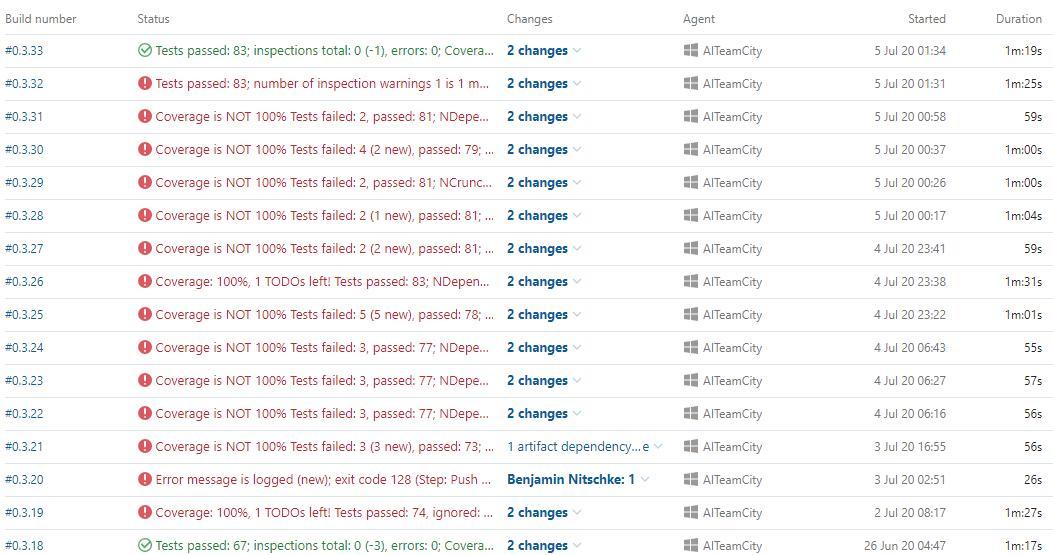
All good now, very fast for development and the CI server will just pull any github repository older than 1h and keep using it for all its tests, later with versioning and https://packages.strict.dev it will work much nicer. Also packages should not just be github repositories, but also be compiled and versioned, which will be much easier to download and use. Currently package management is not very high on the priority list, it just needs to work so testing can go on.

FindType

Once packages work the first obvious use case is to grab Types from them. As explained in the last blog post any public type (any package publicly available and any upper-case type in them) are always available in all .strict files, there is no need to import anything, the whole universe is always available. This is pretty cool when writing code and discovering existing types and features, but it makes type discovery quite a challenge and requires a ton of high level optimizations and caching plus low level code that performs very well going through the code trees. This is the picture from the last blog post: FindType
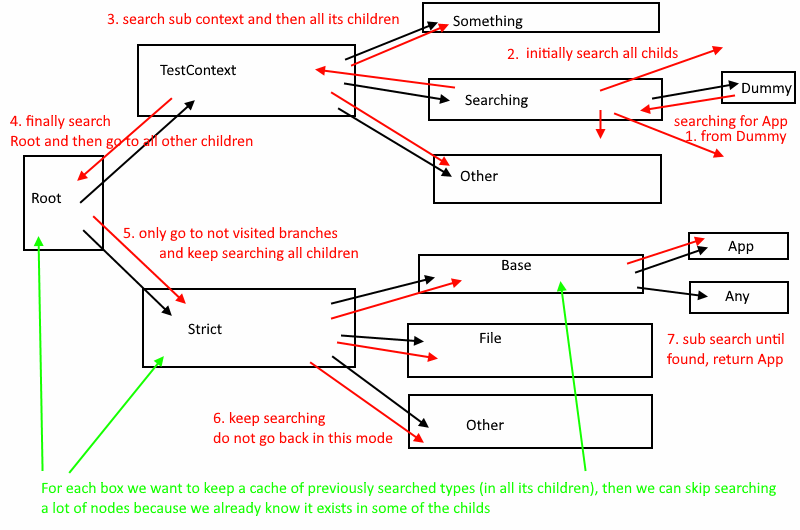
The final implementation is actually just one expression body, but took me multiple days to find all the issues and write a lot of tests to cover all the required features. And even with it working now, the performance is not that great yet, see below for more optimizations.

public override Type? FindType(string name, Context? searchingFrom) =>
    FindDirectType(name) ?? (IsPrivateName(name)
        ? null
        : FindTypeInChildrenPackages(name, searchingFrom) ?? Parent.FindType(name, this));

FindDirectType is just a foreach loop on any type defined in the package directly (not in any sub folder, which are sub packages). It is about twice as fast as a similar Find or FirstOrDefault linq query. It is also usually inlined and only used at a few places:

[MethodImpl(MethodImplOptions.AggressiveInlining)]
public Type? FindDirectType(string name)
{
    foreach (var type in types)
        if (type.Name == name)
            return type;
    return null;
}

Next the FindType method skips over any private name (when a type starts with a lower case letter) because it wouldn't be allowed to use it any other package anyway. The final line first searches all children packages recursively via FindDirectType again, also excluding the context we are coming from (usually our package we jumped into from the Parent.FindType search).

private Type? FindTypeInChildrenPackages(string name, Context? searchingFromPackage)
{
    foreach (var child in children)
        if (child != searchingFromPackage)
        {
            var childType = child.FindDirectType(name) ??
                (children.Count > 0 ? child.FindTypeInChildrenPackages(name, searchingFromPackage) : null);
            if (childType != null)
                return childType;
        }
    return null;
}

Not the prettiest code, but it works and performs its job well. This was actually the most difficult part as I initially used FindType here recursively and had a lot of problem of sub trees not searching the same parent again or parents going into the same children over and over again (lots of StackOverflowExceptions).

Performance

The first rule of optimization is to measure. I pretty much knew that the main issue will be searching from the root package to all children, so this is where I added the cache. This high level optimization gave already a good boost (10-100x faster depending on the use case), it will probably be way faster in the long run when there are hundreds of packages and thousand or million of files.

This is my first line-by-line profiling on the finished working code with all tests green and ContextTests.LoadingTypesOverAndOverWillAlwaysQuicklyReturnTheSame used to check the performance of doing 1 milion calls to FindType. Without the cache it is around twice as slow (and sometimes would time out NCrunch, so the cache is really good), but as you can see from the profile result, that is not really the main problem. FindType Performance Initial
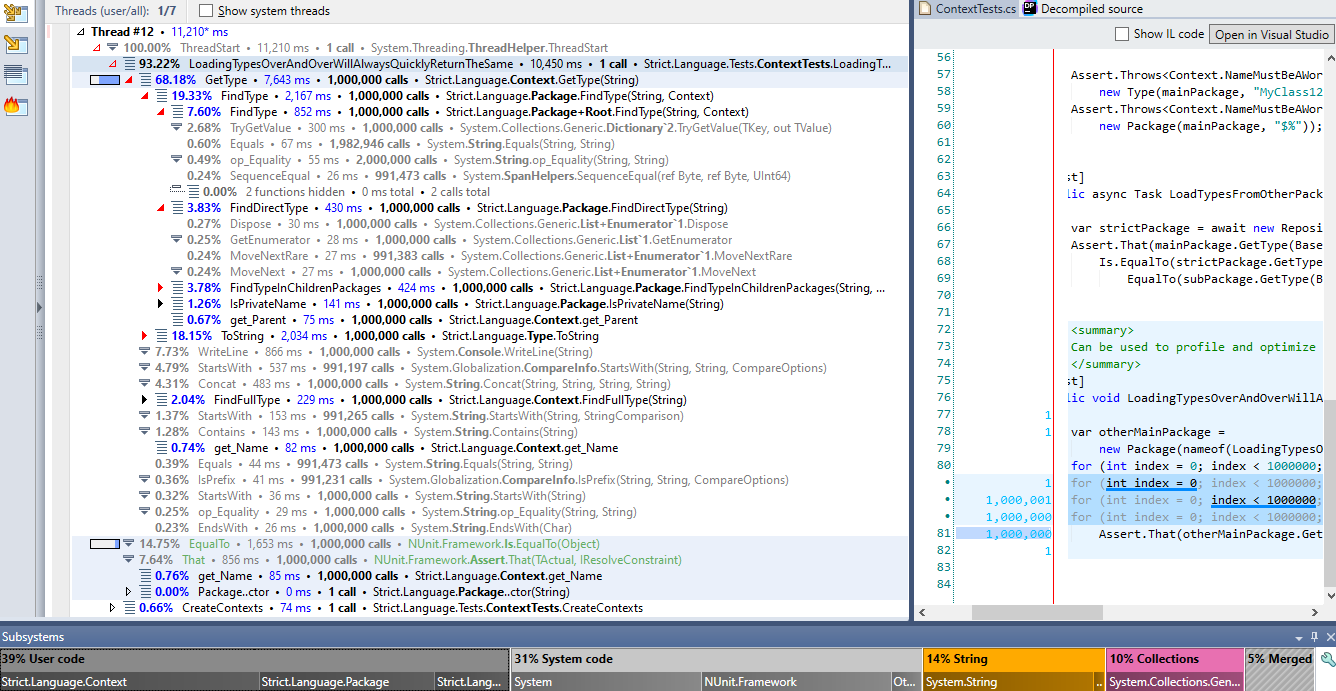
It seems only 39% of the time is even spend in the code I wrote, most of it is wasted on system, string and collection code. First order of business is to reduce the amount of string manipulations done and maybe inline a few more properties and methods just passing data around (with line-by-line profiling there is a lot of overhead, so switched to sample profiling mode).

Digging deeper into the performance results I saw a lot of Enumerators being created and disposed, so I started removing any foreach loop or linq query and if there was any string manipulation or comparison, I tried to remove it or simpify it. Profiling a bit more after some optimizations showed that most time in my example was spent in the Root package checking the cache, which means it works very well already, almost no time is spent in the tree and the only optimization left is to make the cache faster. FindType Performance Dictionary
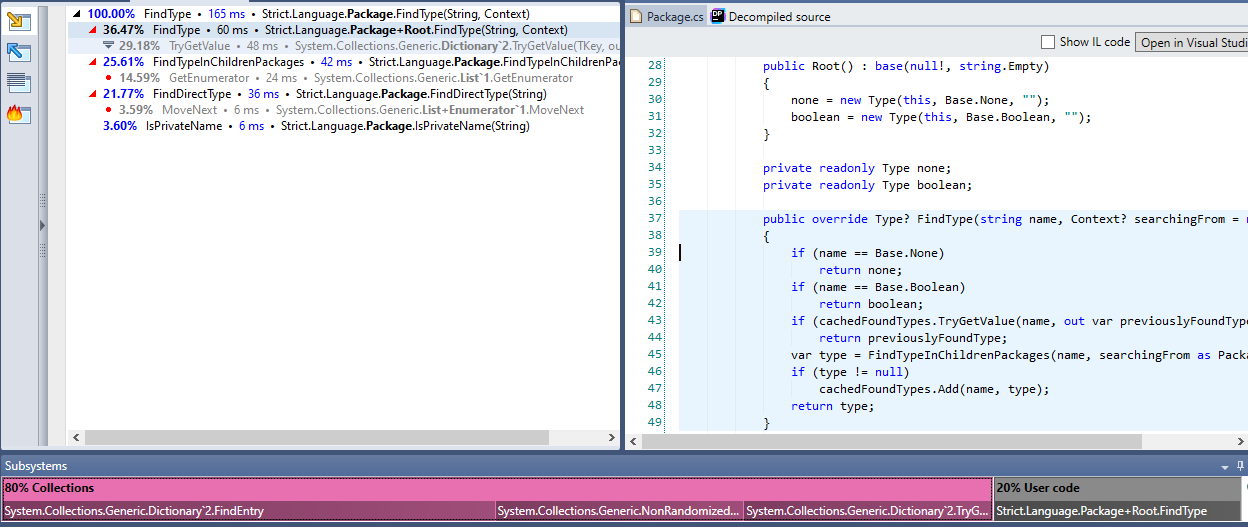
After replacing Dictionary with FastDictionary it was time to profile again and surprise surprise, it was 3 times slower again. I guess .NET core 3.1 is already optimized quite well. I remembered that I could still make string operations about twice as fast by using StringComparer.Ordinal like this blog post talks about, except it didn't help either and made the code about 20% slower than just using non StringComparer methods. Last thing I tried was char.IsLower, replaced it by some custom if code making that part a bit faster as well, but I reverted it back because the .net core is quite optimized and good for this and much more capable than a quick if check (took like 3% of all string checks time, so not important anyway).

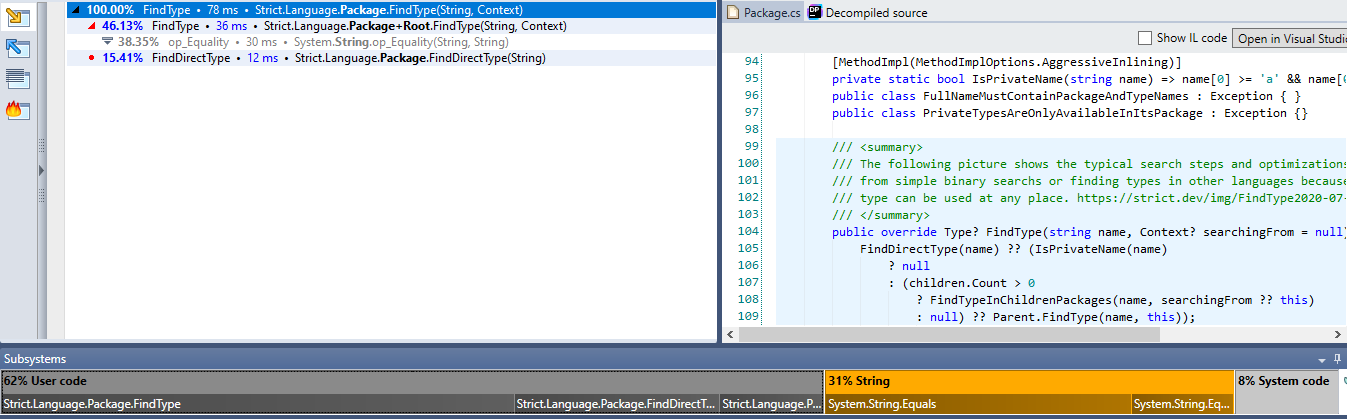
This is the final result, I spent over an hour trying out the above optimizations and just made it worse, so back to this version, good enough (78ms for 1 million FindType calls): FindType Performance Final
Jul 2020 Package Loading

July 1, 2020

Benjamin Nitschke

Tons of changes have been made in the last few days to load packages with all types and all their methods. The reason and use case was trying to put Strict into production already. Having a few unit tests work and experimenting around with simplified language ideas is all nice and good, but useless in the long run if I can't prove it works with actual code in the real world. It is obviously way too early to tell. However nothing is preventing us to write some tests that assume we can run the existing code already.

Initially I tried running some code in a quick self written interpreter (ala virtual machine) like shown in most compiler/interpreter books and getting some simple state machine and calculator parser and interpreter off the ground is not that hard if you have done it a few times. Not that exiciting for me or Strict, so I was looking for a full solution instead. The much older Strict parser and interpreter was written in NRefactory and then later ported to Roslyn (many many years ago when it came out first) and also using Irony for the SNF parsing. That code still works, but is quite complex and not very similar to the new functional way. We also got the strict sdk running in go and that is working fine too, but we don't have an interpreter/virtual machine here yet, just some backend code to generate source code in another language, which has quite a lot of issues as well (e.g. for c++ code to compile each type must work and currently it just isn't done yet).

After some back and forth and trying different solutions I went back to Roslyn, which I know well enough to quickly generate a bunch of code, classes, methods, statements, etc. and run them. Initially getting Roslyn up and running at runtime can be slow (around 1-2s), but the cool thing about Roslyn is that subsequent runs are super fast (in the 10ms range), which makes it good enough for quick testing and running many NCrunch tests in the background all the time. We had 5000+ tests on the Delta Engine backend to generate C++, Objective-C, Java, JavaScript and C# code 6 years ago, initially using NRefactory and later Roslyn on top of our own AST model as well and while it wasn't as fast as the frontend 3000+ tests (which ran in a few seconds), it was fast enough to run all the time and especially on each CI commit. Nowadays computers are faster and tools are better too, our goal is always having unit tests run in under 10ms (with Roslyn the initialization time needs to be excluded as that is not possible to get up and running that quickly, especially generating a new assembly, loading all the required assemblies for analysis, code generation and execution).

Back to the problem at hand: Loading packages, which contain class types and sub packages. Types contain methods and all the statements are in those.

Packages

A good example for a package is the Strict.Base package, which gives us all the base types we usually need anyway (reduced the implementation to what is working now, there will be more types soon).

For now Any.strict (providing ComputeHashCode and IsEqualTo methods) was removed as we don't want to force everyone to implement those or autogenerate them for everything. Every type should get a hashcode, equal checks and conversion to text (ala ToString) automatically anyway.

Strict.Base

  • Any trait: Basis for all classes, is always implemented. Provides to HashCode and to Text (both automatically implemented by default in the compiler, can be overwritten)
  • Mutable trait: Does not implement anything, just provides the compiler with the knowledge that this changes and is not threadsafe (and should be avoided)
  • Number class: Most used type for anything that requires computation, provides number manipulation methods and to / from Text, etc.
  • Character class: Needed for text, basically a number, but will be implemented as utf8 char
  • Count class: Mutable version of Number, which is only used in a single thread, often optimized away
  • HashCode class: Just implements number and stores the hashcode in the implementation (usually as int)
  • Text class: List of characters with a bunch of helpful text methods (implemented as string obviously)
  • Input trait: For getting data, usually from stdin, also reading files or any input device
  • Output trait: For writing data, usually to stdout, stderr or any file, display, data, etc.
  • Log class: implements Output is by default implemented to write to the Console (but the user can provide his own implementation, which would change usages)
  • App trait: Entry point for all apps (there can only be one per package, which must be in the main namespace), requires Run to be implemented

This should be enough to create a console app. If a file is a class or trait usually doesn't matter except when you try to implement it for a new class, where only traits are shown and allowed. Classes are used via has keyword as members. On purpose most complicated methods and features have been left out (localization and culture stuff, we always assume international ISO formats for now). Also no Type, Function or Iterator features yet. Again: We don't want to replace any framework here, just provide the basis so simple programs can be understood and generated by machines.

Any.strict

is(any) returns Boolean
to returns HashCode
to returns Text

Defines all the methods available in any type (everything automatically implements Any). These methods don't have to be implemented by any class, they will be automatically implemented with default behavior if not provided. In the current iteration I removed the method keyword as it is obvious that returns is only used for methods (and None methods are easy to spot as well). Often Any is replaced by a specific type or trait to be more useful in an implementation, for example Input.

Mutable.strict

from(Any)

Number.strict

+(other) returns Number
  +(5) is 5
    Number(3) + 4 is 7
    return self + other
-(other) returns Number
  -(5) is -5
    Number(3) - 2 is 1
    return self - other
/(other) returns Number
    /(50) is 0
    Number(1) / 20 is 0.05
    return self / other
*(other) returns Number
    Number(3) * 4 is 12
    return self * other
>(other) returns Is
    test(0) is false
    test(3) is true
    return self > other
>=(other) returns Is
    test(0) is true
    return self >= other
<(other) returns Is
    test(0) is false
    test(3) is true
    return self < other
<=(other) returns Is
    test(0) is true
    return self <= other

Currently implements all the basic math operations. Conversion to Text is done in that class.

Character.strict

implement Number
from(number)
    test(7) is '7'
    return '0' + number
from(text)
    test("b") is 'b'
    return text.Characters[0]
to returns Text
    test('a') is "a"
    yield self

'7' is not valid yet, maybe Character will become private (thus character), not sure if there are any usecases outside Text for this. Converting numbers to Characters is helpful and getting the first Character from text is also good, same as converting back to Text.

Count.strict

implement Mutable
implement Number
Increase
    Count(5).Increase is 6
    self = self + 1
Decrease
    Count(3).Decrease is 2
    self = self - 1

Here we can test methods that return None because they modify the state of itself (the Number), but we still allow the shortcut testing because we know that we talk about the thing before the None method call. This works everywhere else just as well (even with chaining). ++ or -- are not valid operators in Strict.

HashCode.strict

implement Number

Nothing here yet except a number, probably will stay that way and the Any autoimplementation of to HashCode will just xor each member (with some optimizations for complex things like Text).

Text.strict

has Characters
from(number)
  test(45) is "45"
  return stream digit from digits(number)
    create Character(digit)
digits(number) returns Iterator<Number>
  test(1) is (1)
  test(123) is (1, 2, 3)
  if number / 10 > 0
    yield digits(number / 10)
  yield number % 10
+(other) returns Text
  +("more") is "more"
  "Hey" + " " + "you" is "Hey you"
  return self.Characters + other.Characters

See the blog post June 17, 2020 As Simple As Possible for details. Because Characters ends with s, the type Character is used as an Iterator (readonly array). The + method adds two texts by using the + method for Iterators, which will just create a new bigger list containing both parts.

Input.strict

Read returns Any

Typical example of a trait in Strict, it is super short and easy to read. When loading files Iterator<Text> or Iterator<Number> might be more useful than just Any, but anything is allowed and can be limited when implementing.

Output.strict

Write(any)

Log.strict

implement Output<Text>
Write(text)

Log implements Output via generic specification implements Output<Text>, so only text entries can be written (lines). The log trait is not implemented in Strict yet, the backend will provide us with a ConsoleLog version that will be injected. For testing we need a MockLog thingy as well and I am currently thinking about enforcing writing Mock implementation classes in Strict when using external classes.

App.strict

Run

Another very simple trait just telling us to implement Run, which is the entry point for our package (in case we want to run it, most packages will just be libraries).

Loading Order

All this was just done to force me to implement pre-loading types in a package for the current LoadStrictBaseTypes test, then pre-load each of the implementations, members and methods (which might use other not yet loaded types from the same package). And then do the same for the methods, which are evalutated lazily until they are needed. All types and methods defined in a method body need to be available to compile correctly.

This is not easy at all, I tried several approaches and had to revisit and update this a few times until it all made sense and worked, luckily unit tests helped to stay sane. The following picture shows the typical search steps and optimizations done. It is different from simple binary searchs or finding types in other languages because in Strict any public type can be used at any place. There is much more to be done to make this work by discovering types from packages.strict.dev, more on that later. FindType

Jun 2020 Parsing Methods

June 25, 2020

Benjamin Nitschke

As described last week I tried to simplify the Strict syntax and get some low level type, member and method parsing working in a new simplified respository: https://github.com/strict-lang/Strict

It took a few evenings to make sense of it, now we got a pretty decent simple packages, type, members and method definition parsing system in around 250 lines. No lexing or actual tokenized parsing is going on, Strict is very strict about the syntax and we can assume a lot of things and just abort if a file doesn't match the expected pattern.

However with methods there is obviously a lot of flexibility and even more rules, this approach isn't going to work. However using a full parser is not the best choice either as it allows way too flexible input (ignoring whitespaces, comments, tabs, spaces, extra spaces at end of lines or files), which we want to avoid. The goal is still to get a 1:1 mapping of compiled packages back to their source code without losing anything going back and forth. Plus we want to find one true solution to a problem and not allow many possible ways to do it (which is impossible to archieve, but at least we can limit the search space a lot).

Alternatives

So I looked around in old code (including the sdk in go, older strict versions in C#, lua, python and C++). Code I found ranged from Domain-specific languages, simple state machine parsers, regex parsers, cool projects like Sprache and Superpower and of course the many available full fletched parsers (ANTLR, Irony, etc.), but nothing really fit out of the box. I tried plugging in some old code and got a few lines working, but I wasn't happy with the extra complexity.

Parsing manually

I started back from the beginning with a very simple lexer and spits out tokens, which are then consumed by the MethodParser. Some parts might even be merged because the lexer isn't really doing much and the tokens have to be in an expected order anyway. But error reporting is nice this way and I am not sure about the complexity yet and we might be better off separating lexer, tokens and parsing so applying things like Observer pattern stays easy (have no usecase yet for that, so it is not implemented).

Implemented Tokens

We use the lexer for each line and always start looking at the tabs first, we start at 1 and go deeper for nested statements (if, for, stream), there is no space following this token, but a space must be between every other token except ( and ).

  • test is the first one in any method
  • ( and ) are needed to pass in arguments to test and method calls
  • is is our comparer (ala ==, which doesn't exist in Strict)
  • let allows to create scoped assignments (ala const, reassignment isn't allowed in Strict without the mutable keyword)
  • identifier to name let assignments, also might be a type, unknown here (actually we could know this and classify this different maybe)
  • = assign values to let, has or parameters, any expression more complex than a const value can only happen in methods (we don't have a complex parser at member or parameter level anyway)
  • + example binary operator for now

returns also has been removed in the last post, the last statement in a method must either be a non-return statement and thus makes the method not return anything (None) or return a value of a specific type.

if, for, etc. coming soon.

Statements

  • MethodCall test or any other method call, currently must include () to tell the parser this is a method call as opposed to a member or let
  • LetAssignment assigns a value or expression to a local field
  • Return ends the function and can return a value

As you can see all this is still very easy and allows me to experiment around with different ideas very quickly.

Example

method Double(number)
  test(1) is 2
  let doubled = number + number
  return doubled

The let is obviously useless and would be optimized away (which means the source code would change to return number + number automatically and more optimizations based on that). The whole method doesn't make much sense and probably won't be allowed in some future version, i.e. removing and inlining all code would make it much clearer (especially by just replacing it with 2 * number).

All code can be found at the usual location, coverage is 100%, TeamCity does a lot of nice extra checks and the code is still very clean, nice and short: https://github.com/strict-lang/Strict

Jun 2020 As Simple As Possible

June 17, 2020

Benjamin Nitschke

While exploring options yesterday and today for creating a great editor experience for Strict, I discovered some new options. We already got a VSCode integration that provides basic syntax highlighting and works to write a few lines, but is not a fun experience at all if you are used to fully fletched IDEs. The Strict IntelliJ plugin we recently got working is good enough for some basic Auto Completion / IntelliSense, but there are thousand little issues, which makes the experience not very good yet (which is why it is not released yet and we have noone using or working it daily atm, as opposed to the sdk, Strict and VSCode code bases). I am by no means a Java Guru and don't really like working on top of the IntelliJ platform sdk, so I am unsure when this plugin is gonna be improved.

What sounds very promising is the Language Server Protocol and the growing numbers of implementations. Doing some early experiments a Stritc language server works in Visual Studio Code, Visual Studio 2019 and even IntelliJ (plus a lot of other IDEs and Editors that support it like Emacs, Vim, Atom, whatever people like to use). More on that in the next blog post.

As Simple As Possible, but not simpler

"Everything should be as simple as it can be but not simpler!" - Albert Einstein

While trying to get the Strict Language server plugin up and running for testing, I still noticed some pain points. I am currently preparing the upcoming work for the new employee Mahmoud (starting tomorrow). I can explain away most design decissions, but there are some open issues plus some simplifications that Merlin and me talked about in the past, but are not implemented yet. So instead of continuing with the current sdk in go, I thought why not try starting to bootstrap the Strict compiler directly in Strict .. but no, its not ready yet, I got stuck very quickly.

The sdk code base is already too large for quick experiments, so I just created a new one in c# (where I feel most comfortable until Strict is hopefully more useable later this year) and keep staring at the very old design, the redesign from last year and the redesign from this year (in go). The main thing I noticed is that many checks are just not needed and Strict is very clear on what is valid code and what isn't, so why not get away with no lexing or parsing at the file level at all.

We know a .strict file is describing a type. A type can either be just a trait (think interface) describing what should be implemented, or it is a class optionally implementing one or multiple traits. From the outside it doesn't really matter, you want to use some functionality like Account, Count, Computation, Number, Iteration, etc.

Everthing automatically derives from the Any.strict trait, which looks like this (notice there is no implementation):

method ComputeHashCode() returns Number
method IsEqualTo(target Any) returns Boolean

Either a file contains no implementations, then it is a trait, or it has just implementations, which is most files. Let's look at some String.strict examples while simplifying the language.

Iteration 1

implement Sequence<Character>
has characters
factory From(number)
  From(5) is "5"
  From(123) is "123"
  let result = create StringBuilder()
  while number > 0
    result = "0" + (number % 10) + result
    number = number / 10
  return result

This was an early implementation idea, close to the current String.strict code. You can see it starts with a bunch of tests to make sure what we are doing makes sense and works. Strict enforces to have at least one test condition for every method (which can be any expression returning true, anything else would fail the test and thus compilation).

Here we implement the generic trait Sequence with the Character class, which is used in the next line to create an array (which is immutable like everything else not marked with the mutable trait). Next we have a special factory method called From, which has no method and no return type as it is a factory method to construct this type based on a number.

Next we create a result, which is not a class name, so here we see a type definition for the first time as the compiler can't figure out what we mean by result automatically (string, text, name would all be strings, stringBuilder would be a StringBuilder, but that is long and ugly). The StringBuilder internally keeps a mutable array of characters we can append to, which is useful in this usecase. Now we use a simple formula to add each base10 number at the beginning of result, then reducing the number by a factor of 10. Finally we return the StringBuilder, which has a to method to give us a String, which matches the characters defined above.

Now there are several problems with this code, first of all the number can't be mutated as everything is immutable by default in Strict. We can change that by making it mutable. Next is that we don't even have while loops, there is currently only one form of loops, which is the good old for loop.

Iteration 2

Let's skin the code another way:

implement Sequence<Character>
has characters
from(mutable number)
  test(5) is "5"
  test(123) is "123"
  create result StringBuilder
  for digit in Range(0, Log10(number))
    result = "0" + (number % 10) + result
    number = number / 10
  return result

Ok, here we removed factory, just named it from, which is a reserved keyword anyway to convert stuff to something else. We also added a mutable to the number (which is still of type Number) to allow changing it in our loop. The tests look better as they directly tell us what we are asserting (btw: complex tests with multiple lines can be written as indented code blocks like everything else). Also calling yourself and trying the method name again and again isn't produce, lets just use the test keyword and pass the parameters directly in here.

Next I have renamed let to create and removed all the assignment stuff and the parentheses as there is nothing we pass as parameters. The loop is now a for loop and got the Range going over the digits of the number and still does the same logic inside the loop.

Iteration 3

This is still not very functional and it seems I am still trying to low level optimize, which should be the job of the compiler and not the coder. Let's try to go a more functional approach.

implement Sequence<Character>
has characters
from(number)
  test(45) is "45"
  return stream digit from digits(number)
    create Character(digit)
method digits(number)
  test(1) is (1)
  test(123) is (1, 2, 3)
  if number / 10 > 0
    yield digits(number / 10)
  yield number % 10

Here we use streams, which are not documented well yet. I just added the streams page. Basically they grab any array, collection, sequence or data and pass it though the pipe in the lines below. Here we simply create a Character for each digit (which does the "0" + number thing for us). The stream combines it all back to an array of characters, which automatically matches our String we wanted to build (any type can be constructed by supplying the has members, no need to write any method, constructor or factory like that, as usual this is forbidden in Strict ^^).

Iteration X

This is not done yet and will be changed many times. I am currently just experimenting with parsing the above code and see if the AST that pops out makes any sense.

Anyway, methods contain code that needs to be parsed, everything else (implement, has, from, method) we can make up from simple rules, which is what I am currently trying at https://github.com/strict-lang/Strict

One final note: I completely removed imports as the Context that is used to parse a file knows all types already and if any unknown type is used in a .strict file, the parsing (and thus compiler) stops. There is probably some ordering that needs to be done and the optional build.yml file needs to allow users to point to more than just the default repository for all known types.

Summary

Just two nightly code sessions with most of the time thinking about simplifications what what makes sense, this repository will stay in flux for some time and should not be considered stable (the sdk repo works and is usable and any bugs there we will still fix till the new repo is remotely usable). The main goal here is to make the editor support and language server implementation much easier and also think on what makes sense while adding some code we can compile and run soon (using as much as possible from existing blocks).

Todays goal is just to get it all green on TeamCity CI (Continuous Integration), which is still complaining about some ugly comments, some small issues and not having 100% coverage yet .. no biggy.

Jun 2020 Back to blogging

June 11, 2020

Benjamin Nitschke

My employee Abir poked me to blog more about Strict and the decisions I recently took for the IDE development. My old blog at https://BenjaminNitschke.com (2004-2016) is pretty much dead and I never found time to continue talking about Game Development in recent years, which is mostly because our company just didn't much game development work. All paid work for the past 5 years has been outside of creating games (aside from one mobile game app exception), we still did improve the Delta Engine, participated in Game Jams, worked on our Towers RTS game and stayed connected in the space. However, this was only if there was free time and paid work was always more important to keep the company and employees alive. Now we are doing much better with 10 employees at Delta Engine atm and our AI and Robotics work is getting off the road and use cases are in sight, however, no employee I currently have is a game developer atm (including me). So my focus in life will be work plus https://strict-lang.org

I am happy to announce that a new employee Mahmoud will help me will all this starting next week, continuing work on Strict, the IDE, compiling, SCrunch, etc. I am pumped to get more speed on the road again.

IntelliJ vs Visual Studio Code

Merlin and me had this discussion earlier this year already, it was actually about which IDEs Strict should support. Merlin is coming from the Java world and really likes IntelliJ, which I agree is the most productive IDE for Java and other JDK languages and we also use Goland to develop https://github.com/strict-lang/sdk, so we decided to focus on that first. I use Visual Studio day in and day out and I am by far the most productive in C# utilizing many tools (ReSharper, NCrunch) and workflows that only exist in Visual Studio. I did actually write an earlier version of strict with the Irony Compiler Kit in .NET over 10 years ago and started writing a Visual Studio Extension, but it was not easy to fix all issues and constantly add features. We also worked at Delta Engine on Visual Studio Extensions around 7 years ago and it was a mess and very hard to maintain. I checked back around a year ago and it is still not a great development experience. So IntelliJ was choosen instead, which is a fully fletched IDE (and since we are using ReSharper, similar in features and hotkeys to what we use daily in Visual Studio) with many amazing features we want for Strict and the platform sdk docs are very good as well: https://www.jetbrains.org/intellij/sdk/docs/intro/welcome.html

The downside to IntellJ (and the Java world in general) is the complexity, there is way too much code, so many little issues you have to know about, so many annoying patterns and copy+pasting until stuff works, which is very different from what we want to archieve with Strict. Development slowed down to a halt, Merlin was annoyed, I didn't ever work with IntelliJ plugins and the learning curve is steep. I created a freelancer project to finish the blocking issues and found a developer that could finish it after a lot of back and forth: https://www.freelancer.com/projects/java/Add-Smart-Auto-Completion-IntelliJ/details

The IntelliJ plugin works, but it still sucks (Auto complete shows the same member we are just defining, there is no filtering, most things shouldn't pop up based on the context, etc. while still way better than any dynamic language or javascript, it is not like the fleshed out intelligent Auto Complete from good languages like C# or Java). It will take many iterations to make nice and useful and I don't really see a light at the end of the tunnel, feels more like a never ending painful story. We might continue on this road, but it won't be the top priority.

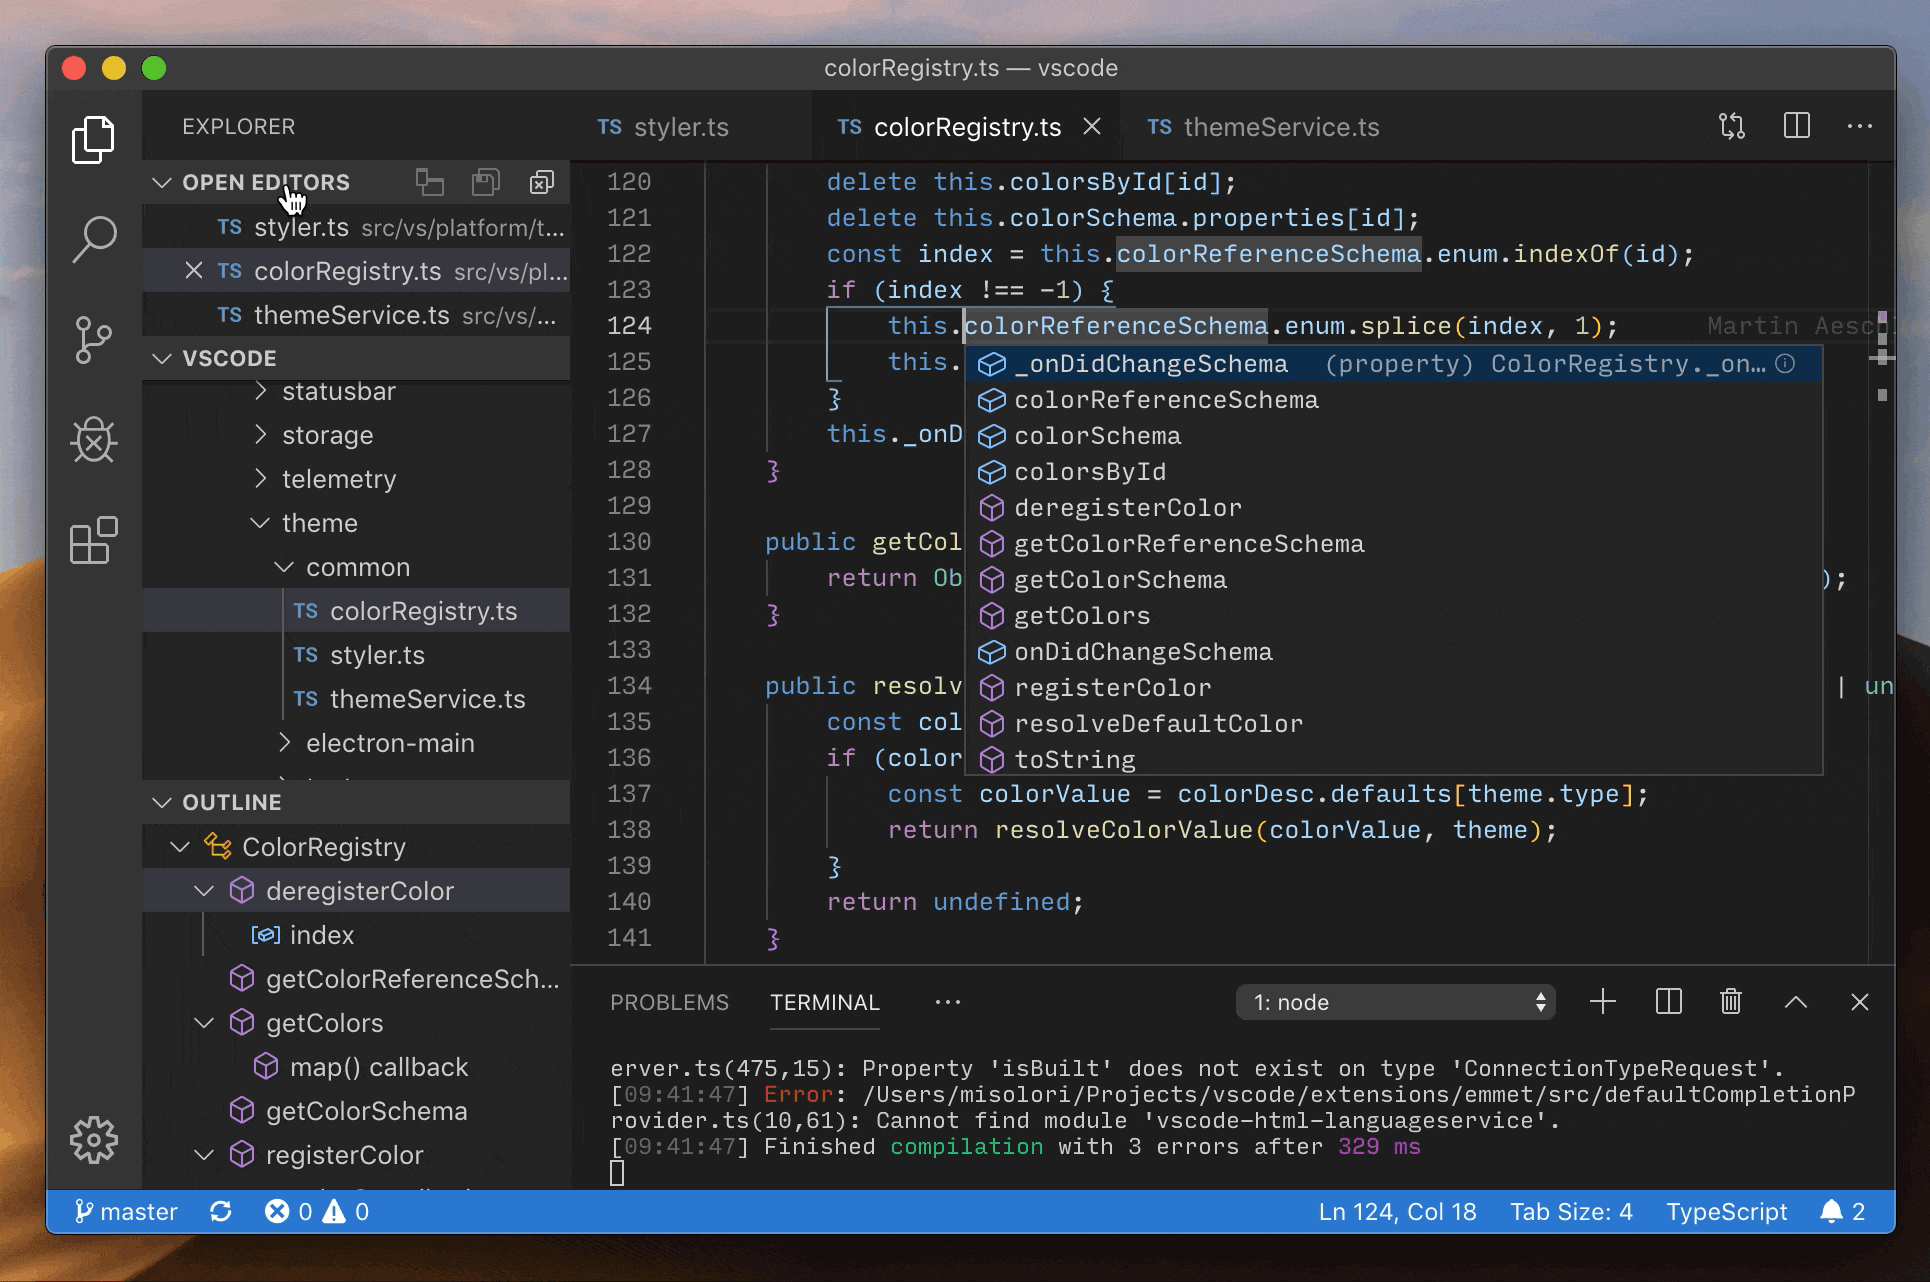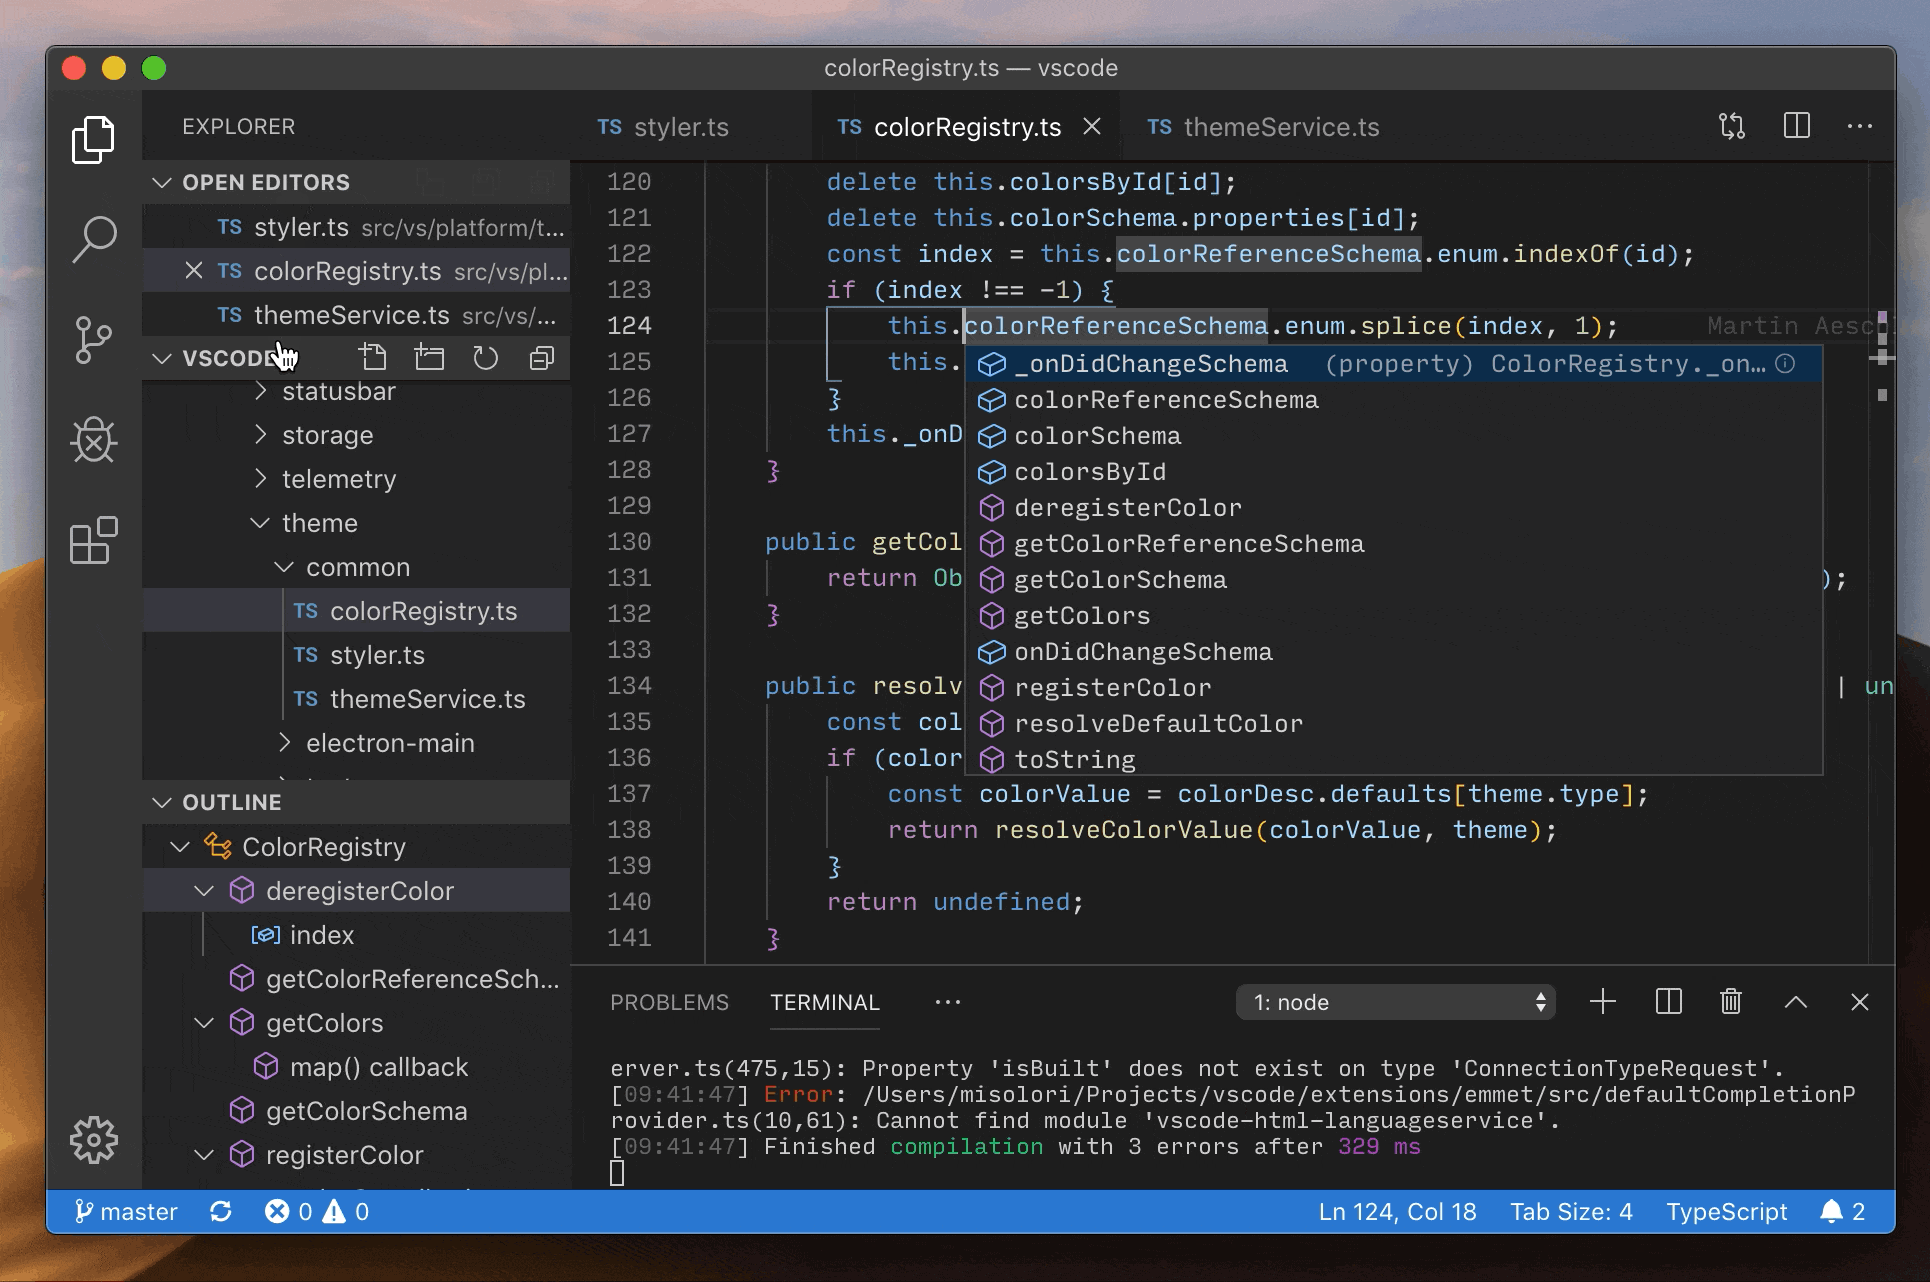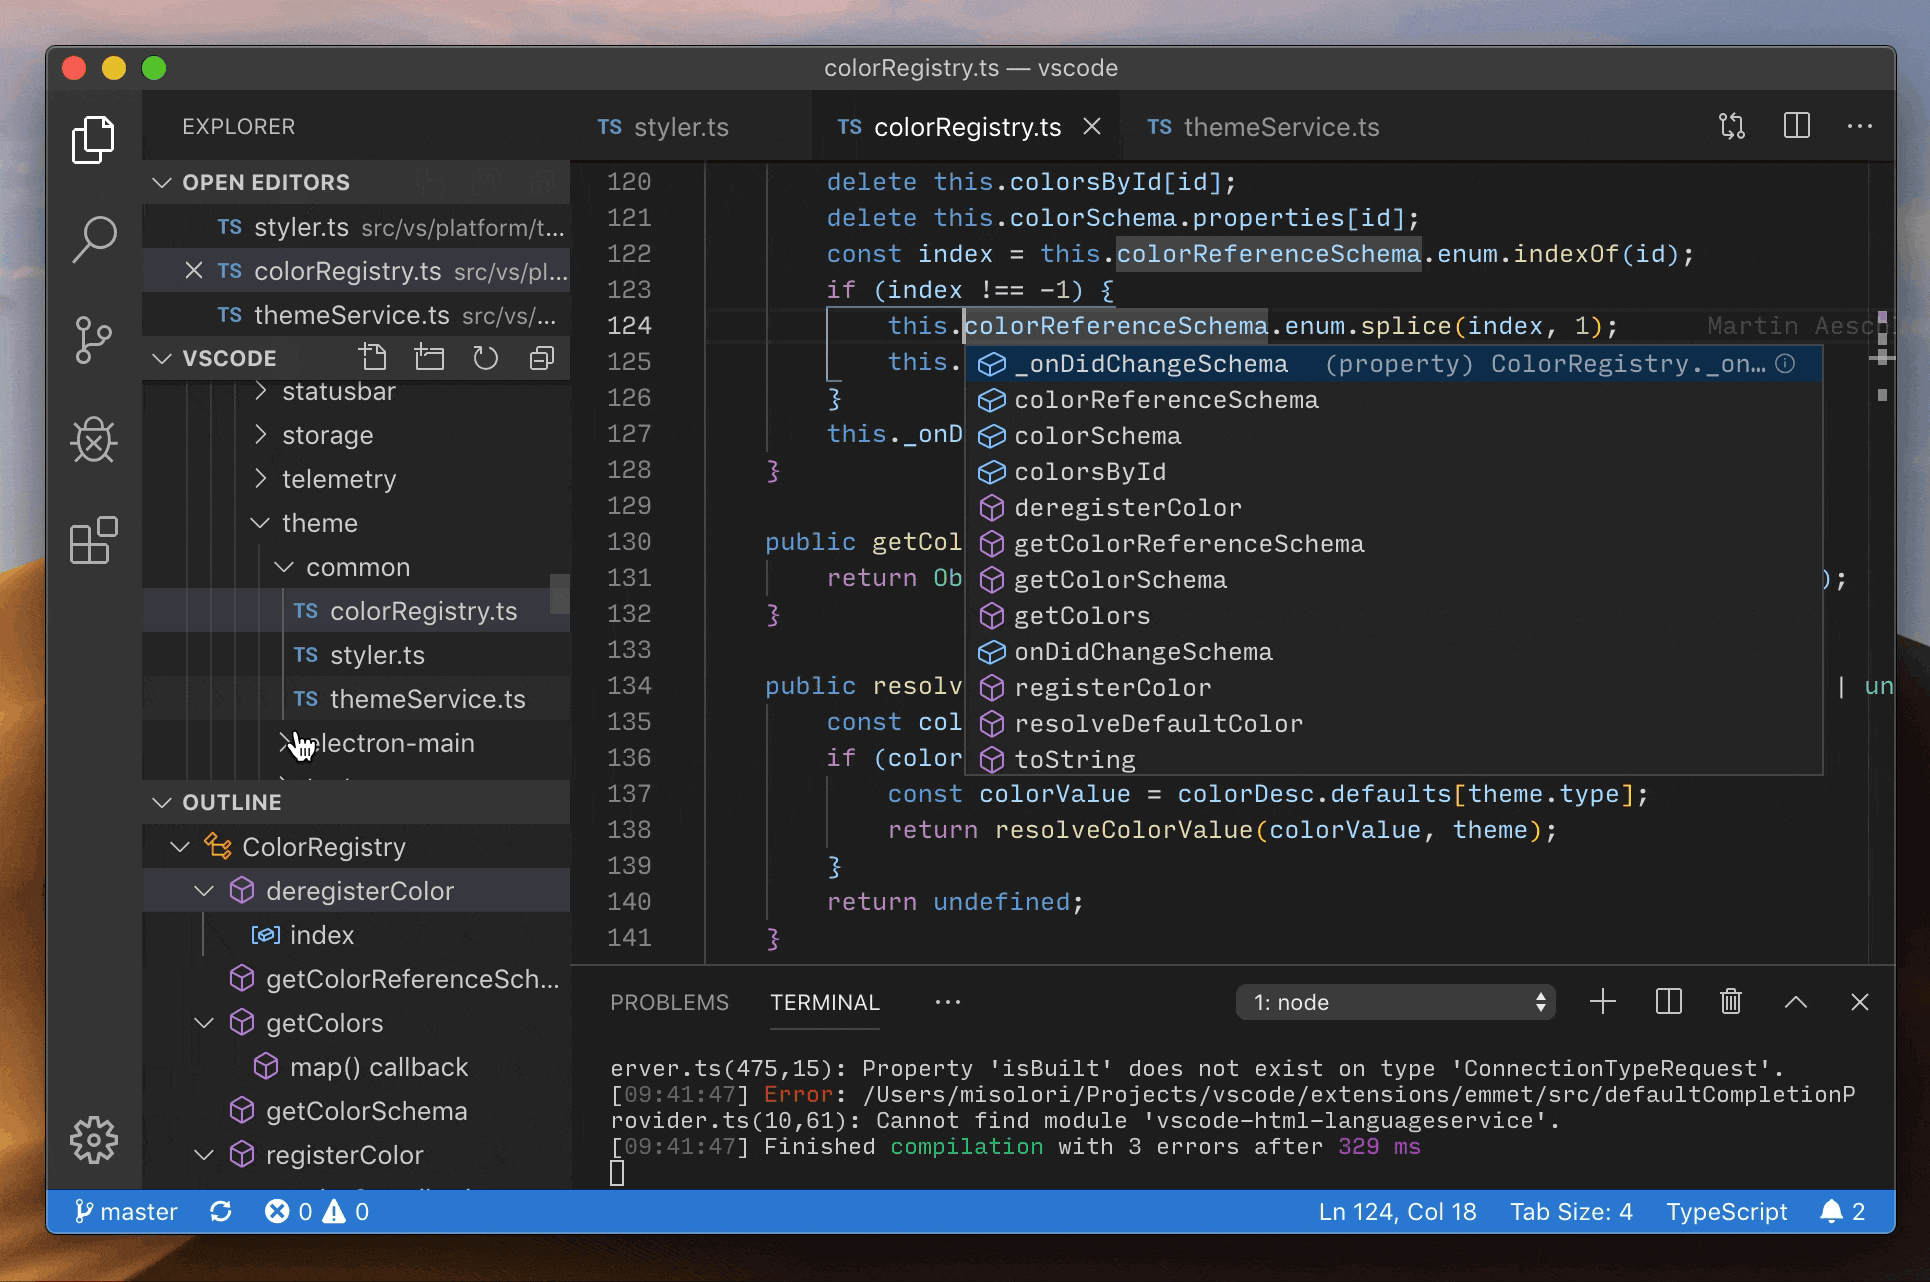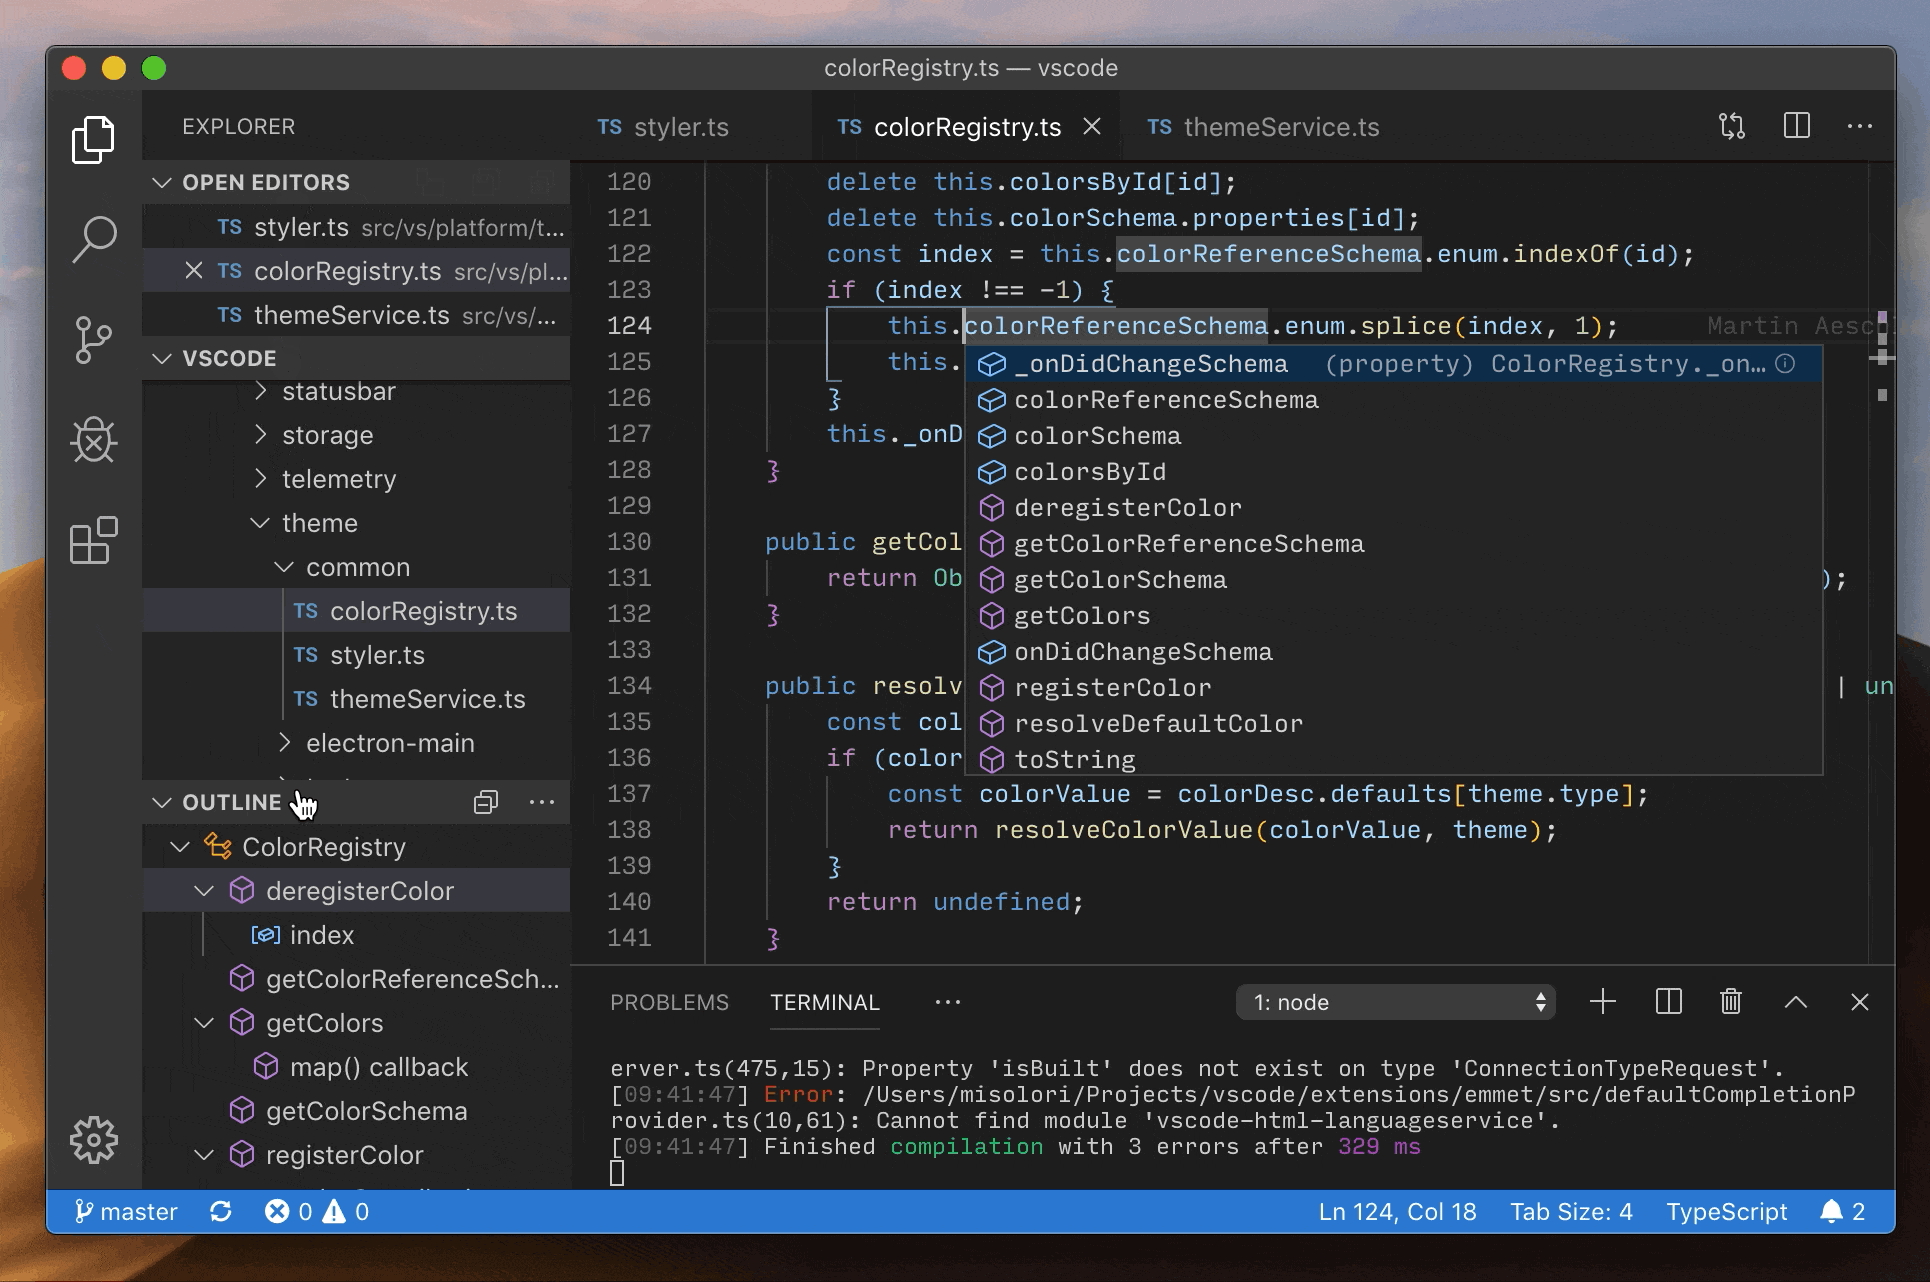
We also have created a simple Visual Studio Code plugin to support the .strict file format and syntax highlighting: https://github.com/strict-lang/vscode-strict Since Visual Studio Code plugins are written in JavaScript (or TypeScript, which becomes JavaScript), it wasn't really our main choice to write strict parsing/lexing/SCrunch/etc. with such a messy language like JavaScript .. at least this is what I thought earlier this year. After creating a simple Visual Studio Code plugin using TypeScript (very nice) with the server language service that can be written in any language and just needs a thin client rpc connection from TypeScript, that already looks more promising. The main reason we wanted to support Visual Studio Code anyway is the way bigger community around it. It is small, slick, fast and most web developers know and use it already. There is also a new cool feature from github to run the VS Code IDE in the browser for your github project, which is amazing (not out yet, we are in the beta and while still cumbersome with azure setup, the idea fits extremely well to Strict): https://github.com/features/codespaces/

Comparision

alt text

IntelliJ

  • Very powerful, full fletched IDE
  • Not as open and free as VS Code, thus smaller community outside of the Java world, but still work be free for Strict users (IntelliJ community is free)
  • Great docs, lots of people comfortable with it
  • Really Bloated, I really hate downloading 500MB+ just to launch gradle, grab some new sdk, get some IntelliJ version, etc.

alt text

Visual Studio Code

  • Free, small, slick, open source
  • Greatest plugin ecosystem of all IDEs, really small and fast plugins, similar to Chrome plugins, just nice
  • Not as powerful, haven't seen a really nice IDE experience or language implementation as good as Visual Studio or IntelliJ provide

alt text

Visual Studio 2019

  • Community edition is free as well
  • IMO best IDE for the past 20 years by far, pretty much any professional C# or C++ developer uses it (especially game developers, which is the world I am coming from)
  • Lots of commercial and professional plugins
  • Not as popular in the open source community, also most of the things are stuck in their world, you can't just reuse features of some plugin as they are mostly closed source
  • Extension development is not so nice and not so many people do it, smaller things are ok, but complex stuff is painful

Summary

Going the Visual Studio Code route for now, I will post more when I find some time this or next week about my little language service and running it with Strict.

May 2020 Slow and not steady

May 4, 2020

Benjamin Nitschke

The corona pandemic didn't affect us much, but we did do home office work for most employees away from the Delta Engine company since mid March, for some employees things worked out great, for others it wasn't a very productive time. Also talking about ideas and just putting stuff up on whiteboards just works much better in person. Things are back to normal now and the AI and robot hardware work is heating up at the office ^^

Sadly progress on the Strict IntelliJ plugin is very slow and Merlin, who did a lot of the early work recently and was leading the IntelliJ platform sdk work, is stepping back a bit. I will try to find a replacement and try to finish the IntelliJ plugin work. We didn't have much time to work on the website, the language changed quite a lot into a more functional style, while still being fully declarative and test driven. The IntelliJ IDE is still being worked on and once that is finished the language will go into a much more useable state and we can let it lose on some employees.

Apr 2020 Sdk going open source

April 8, 2020

Benjamin Nitschke

Strict was always supposed to be open source, Merlin pushed a bit to get some parts released. Upcoming work is to write the low level language framework (apps, io, logs, math, files, etc.) and to allow anyone writing any code, the strict compiler needs to be out there as well, so we decided to release the https://github.com/strict-lang/sdk finally on github (the compiler is currenty all written in go and can't bootstrap itself yet).

I also ran a logo contest last month and we created some basic graphics for the website, ide, libraries, file types, etc. Kirsten still wants to do some mascot work when she finds time and we are still all adding more stuff to the https://strict-lang.org/docs/Overview alt text

Feb 2020 Still work in progress

February 24, 2020

Benjamin Nitschke

We didn't have much time to work on the website, the language changed quite a lot into a more functional style, while still being fully declarative and test driven. The IntelliJ IDE is still being worked on and once that is finished the language will go into a much more useable state and we can let it lose on some employees.

Originally I wanted to post a roadmap, but since we don't really have a development team working on this and I pretty much do this in my spare time plus getting some help here and there, development speed is still slow. The current focus is getting IntelliJ IDE up and running with our own parser/lexer in the upcomming months. Write small hello worlds in the console is fine, but for any productive work an IDE is needed imo. My exployees at Delta Engine are also my guinea pigs for Strict and without ReSharper and NCrunch we just ain't gonna get happy.

So next up is adding SCrunch working to make writing TDD code even more fun, after that work on backends (C#, C++, Java) should be completed and finally work on Stricti can start (which is the basic idea letting AI Neural Networks try to generate some simple code based on the user just writing tests for the code to be generated).

Jan 2020 website is up

January 17, 2020

Benjamin Nitschke

This blog is all about the development of the Strict programming language, which has the main goal allowing computers/AI to understand and write their own code with it. While Strict might look similar to C like languages or python, go, lua or lisp, clojure or scheme because of its basic functional nature, it differentiates from all programming languages I know about by the simple fact that it is 100% TDD (test driven development) and the code being very strict on what you can and can't do, thus often leading to only one correct implementation. At least that is the idea so far.

Earlier versions of strict already existed around 10 years ago (shoutout to Irony Compiler Kit) and ~20 years ago on paper/early concepts and while they worked as a very simple language, they were not useful or productive at all. It is very hard to build an ecosystem around a language, so the new strategy for this year is to make use of the Strict language early at work (generating c++, cleanup c#, connect libraries, useful stuff). Also the goal is to create a language that can be written by computers, not to build frameworks, libraries or support general user usecases. As long as it is possible we will try to utilize existing languages, libraries and frameworks by simply calling them, not reinvent them. The Strict backend can generate C++, C# and Java code anyway, so this part should be easy as long as there is no close integration needed (like database or UI code, let's not do that right now).

Today was about setting up this website: After trying out https://jekyllrb.com/ and many themes and plugins after checking out the even more complex https://gohugo.io/ it turns out these are not good fits for the Strict language, which should be easy to install and work immediately. https://docusaurus.io/en/ is a project that is installed with one line and works instantly after downloading all the dependencies automatically, on any platform that supports node.

Well, not much on here yet, we will add documentation over time and get more speed on the road in 2020.

My previous blog (2004-2016): http://BenjaminNitschke.com

← Prev
Docs
The VS Code ExperienceGetting StartedPlatformsBuilt with StrictLanguage GuideCheat SheetCoding Style
Source
Base TypesArchitectureExamplesQwen3 and Machine LearningC and C# Interop
More
BlogGitHubIssuesVS Code ExtensionWebsite SourceStar
Copyright © 2000-2026 Benjamin Nitschke